Methodology
How BotSharkdecides a score
BotShark looks at public posting behaviour and asks a practical question: does this account look automated, coordinated, or farmed? The answer is a 0–100 likelihood score, a plain-language tier, and a report that shows why — not a black-box “bot / not bot” label.
01
What we measure (and what we don’t)
Behaviour, not opinions.
We measure behavioural likelihood — posting rhythm, engagement shape, content reuse, profile cues, and network patterns that commonly show up on automated or coordinated accounts.
We do not score ideology, “truthfulness,” or guilt. A high score means several independent signals lined up with automation or coordination heuristics. You still decide what that means in context.
Coordination signals ignore the platform’s own media hosts and common destinations (YouTube, major news, other socials). A shared destination counts only when it is rare and shared by three or more accounts in the library. That makes catch-rate for destination sharing a lower bound: generic hosts are out on purpose.
Each report names the checks that fired, in plain language, with the posts or metrics behind them. If we can’t show the work, we don’t pretend the evidence is stronger than it is. Every report stamps the ruleset version that produced it, so a score from last month is not silently re-explained by whatever the rules say today.
02
The pipeline
Four steps, the same for every account.
01
Collect
Public profile metadata and recent posts and replies from X. Data for X scans is supplied by Sorsa. X verification badges (gold/grey) come from twitterapi.io.
02
Extract
Behavioural features across the same five groups every report shows. No content-opinion inputs.
03
Score
Explainable rules add points when their conditions match. Overlapping rules don’t double-count.
04
Explain
The report lists what fired, in plain language, with evidence — plus confidence about data coverage.
03
What goes into the score
Five groups — the same five every report shows.
BotShark is not a machine-learning classifier that “feels” bot-like. It’s a stack of inspectable rules, each asking a specific question about public behaviour, grouped the same five ways every report shows. Independent checks add points; overlapping checks that tell the same story don’t stack; the score is capped at 100. Confidence — how complete the sample was — is reported separately and never folded into the score. The score adds up flagged checks only. Checks that are not flagged do not lower the score.
A high reply ratio is not a farm on its own. A farm shows templates, duplicate text, or a high mismatch rate. Posting rate alone tops out below “likely a bot”; the top rate tiers need a second behavioural tell.
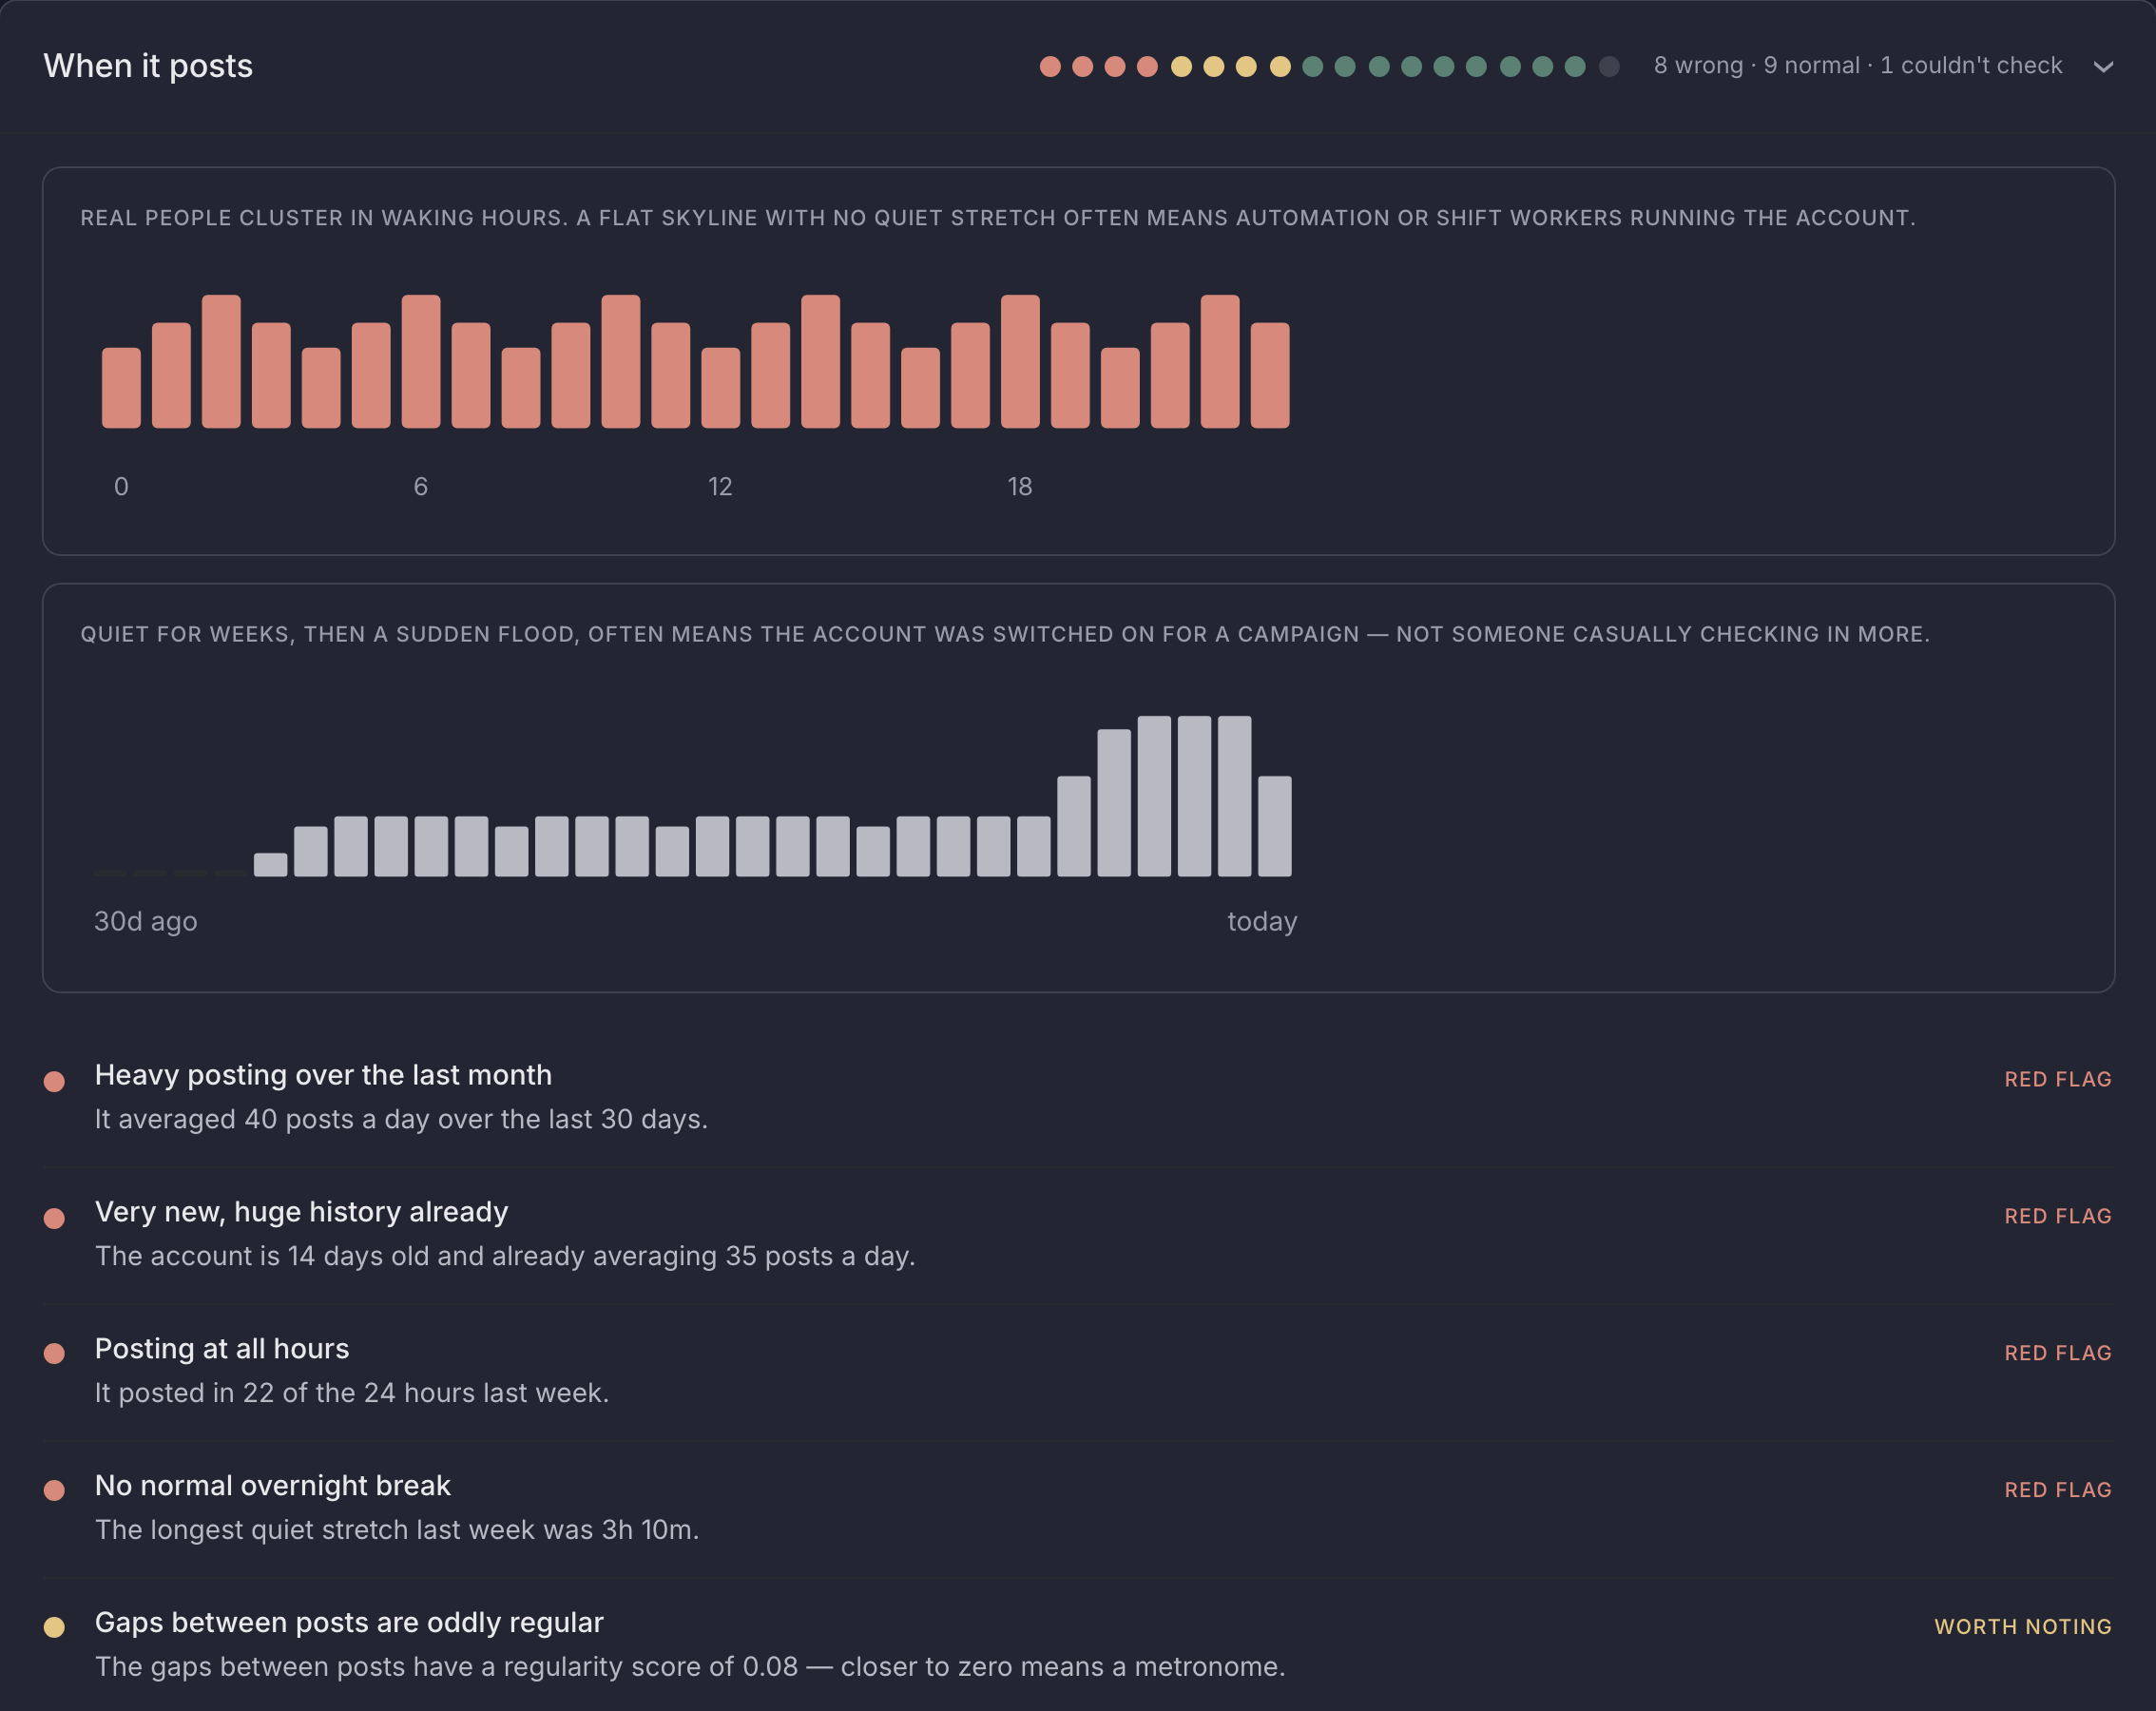
When it posts
Posting rhythm around the clock, overnight gaps, bursts, and volume over time.
Most people go quiet for 6–8 hours overnight and have a clear daytime peak.
What it posts
Original words versus copies, repeated templates, link and hashtag habits.
Most people write around half their own posts and almost never repeat one word for word.
How it talks to people
Replies out versus replies back, and whether replies fit the post they sit under.
Most people get roughly as many replies as they send, about things they actually read.
Who it follows and who follows it
Follower shape, growth spikes, and how the audience behaves.
Most people are followed by about as many accounts as they follow.
The profile itself
Account age against activity, default avatars, bio wording, name changes.
Most people’s profiles grow slowly and read like a person, not a pitch.
These are the groups, not the rule catalogue. The individual checks, numeric bands, and weights stay unpublished — each report names the checks that fired for that account, which is the part a reader can verify.
04
What’s inspectable
Reports show their work. The rulebook stays ours.
Each report lists the checks that fired for that account, in plain language, with the posts or metrics behind them, and stamps a ruleset checksum in the footer — a score from last month is never silently re-explained by this month’s rules.
We do not publish the rule catalogue or the scoring curve — the individual checks, numeric bands, exclusion groups, and predicates — as a tourist page. A journalist citing a report should use that report’s fired checks and ruleset version, not a master table of every weight.
05
Likelihood tiers
Same colours as the band on every report.
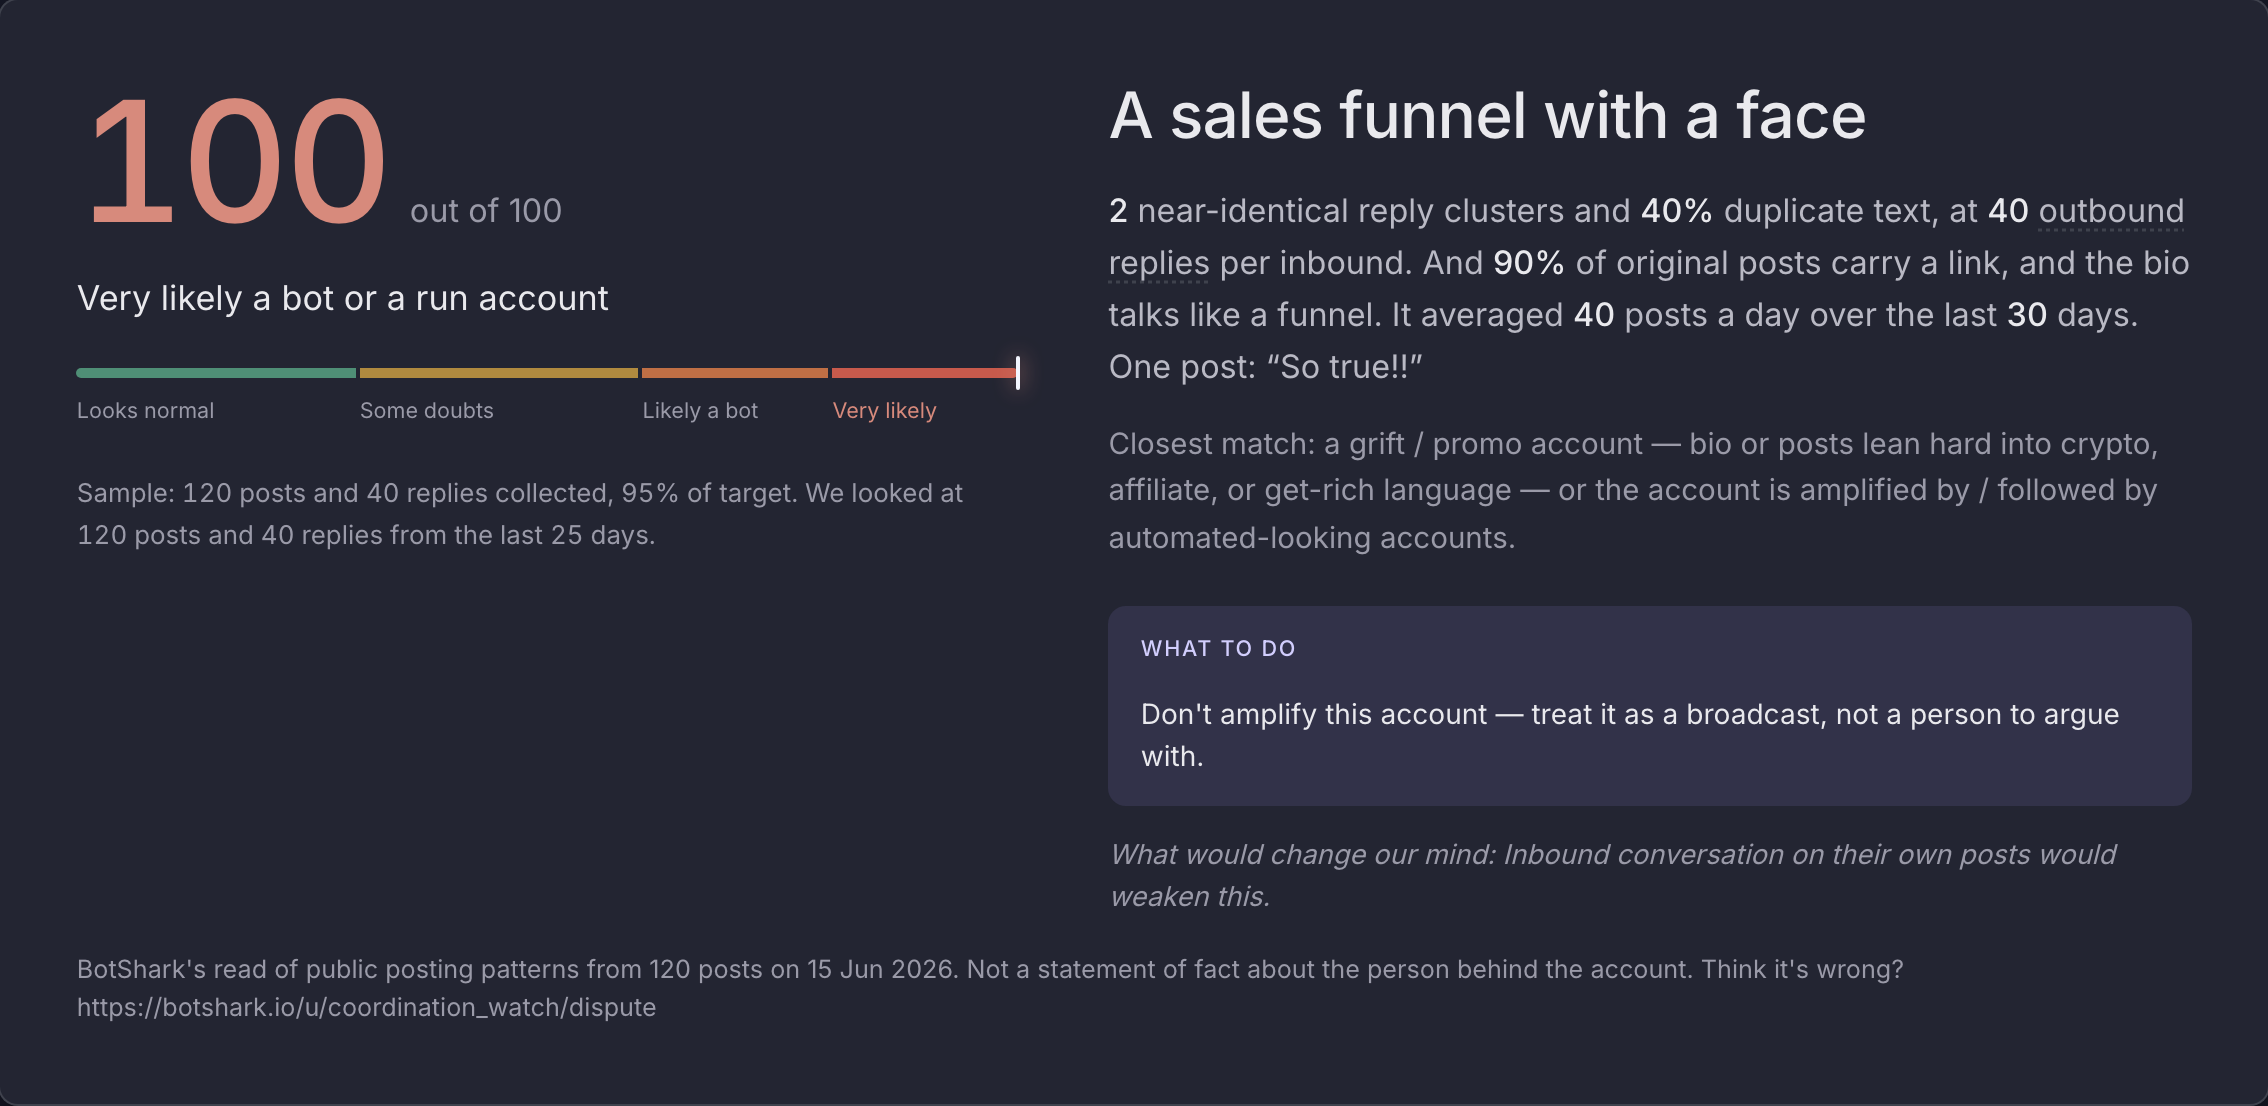
The number maps to a tier so readers don’t have to memorise cutoffs. Tiers describelikelihood of automation/coordination patterns, not a courtroom verdict.
0–29Low likelihood
In what we sampled, this mostly behaves like a normal user. That doesn’t mean they’re trustworthy — just that we didn’t see strong bot patterns.
30–59Moderate likelihood
A mix of habits that raise an eyebrow and some that look ordinary. Read the details rather than going on the score alone.
60–79High likelihood
Several parts of the account line up with how bots and amplifier farms usually behave. No single number proves it, but the overall shape is suspicious.
80–100Very high likelihood
Posting habits, engagement shape, and content all tell the same story — this doesn’t read like someone using the app for themselves.
06
What’s in a report
Everything a citation needs.
A finished report includes the score and tier, the strongest signals in plain language, category breakdowns, charts (posting rhythm, engagement mix, and related views), and caveats when the sample was thin. Every check is flagged, not flagged, or not assessed. The score adds up flagged checks only.
Every scan reads the account’s recent posts and the replies under them, and samples who follows it, who it follows, and who amplifies it — 200 posts, 100 replies, plus those network samples. Every plan uses the same rules.
Treat the report as one investigative input alongside primary sources and human judgement. See neutrality before citing findings publicly.
07
Limits (read these)
What a score can and cannot tell you.
- Not enough to tell is three situations. Too few posts (fewer than 20 authored in the sample; replies count); collection incomplete — retry; or a language we cannot read yet. Never “the account is empty” when the fetch failed.
- Empty timelines hide bots. Some automated accounts have little or no visible posts in the window we can collect. We can’t invent posting patterns that aren’t there — those cases need network/history cues or a deeper rescan, not a fake high score.
- Public data only. Private accounts, deleted posts, and platform rate limits bound what we see.
- Humans can look weird; bots can look polished.A low score is not a character reference. A high score is not proof of intent.
- We revise rules when the data disagrees.Thresholds and weights are tested against labelled known-bot and known-human accounts, then updated when a rule overfires or underfires.
08
How we check the scoring
Measured on a labelled set. Re-run by hand before a weight change.
This labelled eval is 112 days old (refreshed 14 July 2026). Treat the tables as the last measured snapshot, not a live accuracy claim. The eval is re-run by hand with botshark-ops eval-scoring before any weight change, and this page shows that run’s date.
How the labelled set was made
“Human” labels are accounts from the operator’s own following list, auto-labelled as false positives. “Bot” labels are handles the operator supplied as known automated or farmed accounts. The same set is used to tune rule weights — there is a train/holdout split for decision-grade suggestions, but this published table is the full labelled set as of 14 July 2026. It is not a random sample of the platform. The eval is re-run by hand with botshark-ops eval-scoring before any weight change, and this page shows that run’s date.
We run BotShark on that set and ask two everyday questions at each score cutoff:
- When we call something a bot, how often are we right?
- (Researchers call this precision.) At score ≥ 60 on accounts with posts we could score, that was 100% (roughly 85–100% of the time).
- Of the known bots in that set, how many do we catch?
- (Researchers call this recall.) Same cutoff: 67% (roughly 50–80%). Library destination and paraphrase recall is understated: platform-CDN destinations were purged and never count. This published recall is not the product recall of the shared-destination checks.
Current labelled set: 166 accounts (123 bots, 43 humans). 90 had empty timelines when collected · eval refreshed 14 July 2026. The ranges in the tables below are 95% confidence intervals — a statistical “we’re not pretending one sample is exact.”
Accounts with posts we could score
The set we recommend citing. Skips labelled bots that had an empty timeline when collected — those cannot show posting patterns, so including them makes “catch rate” look worse than it is.
| If score ≥ | Right when we say bot | Known bots caught | Balance (F1) |
|---|---|---|---|
| 40 | 73% (56–85%) | 73% (56–85%) | 0.73 |
| 50 | 88% (71–96%) | 70% (53–83%) | 0.78 |
| 60 | 100% (85–100%) | 67% (50–80%) | 0.80 |
| 70 | 100% (84–100%) | 61% (44–75%) | 0.75 |
| 80 | 100% (83–100%) | 58% (41–73%) | 0.73 |
Accounts that never looked empty
A stricter slice: labelled accounts whose timelines had content throughout collection.
| If score ≥ | Right when we say bot | Known bots caught | Balance (F1) |
|---|---|---|---|
| 40 | 73% (56–85%) | 73% (56–85%) | 0.73 |
| 50 | 88% (71–96%) | 70% (53–83%) | 0.78 |
| 60 | 100% (85–100%) | 67% (50–80%) | 0.80 |
| 70 | 100% (84–100%) | 61% (44–75%) | 0.75 |
| 80 | 100% (83–100%) | 58% (41–73%) | 0.73 |
Every labelled account
Includes empty-timeline bots. Useful for honesty about coverage gaps — not the number to quote as “how good is BotShark at catching bots.”
| If score ≥ | Right when we say bot | Known bots caught | Balance (F1) |
|---|---|---|---|
| 40 | 74% (57–85%) | 20% (14–28%) | 0.32 |
| 50 | 89% (72–96%) | 20% (14–27%) | 0.32 |
| 60 | 100% (85–100%) | 18% (12–26%) | 0.30 |
| 70 | 100% (84–100%) | 16% (11–24%) | 0.28 |
| 80 | 100% (83–100%) | 15% (10–23%) | 0.27 |
These tables package measurements from our labelled eval runs. They do not invent new claims. For a walkthrough of the product surface, start with the sample report.